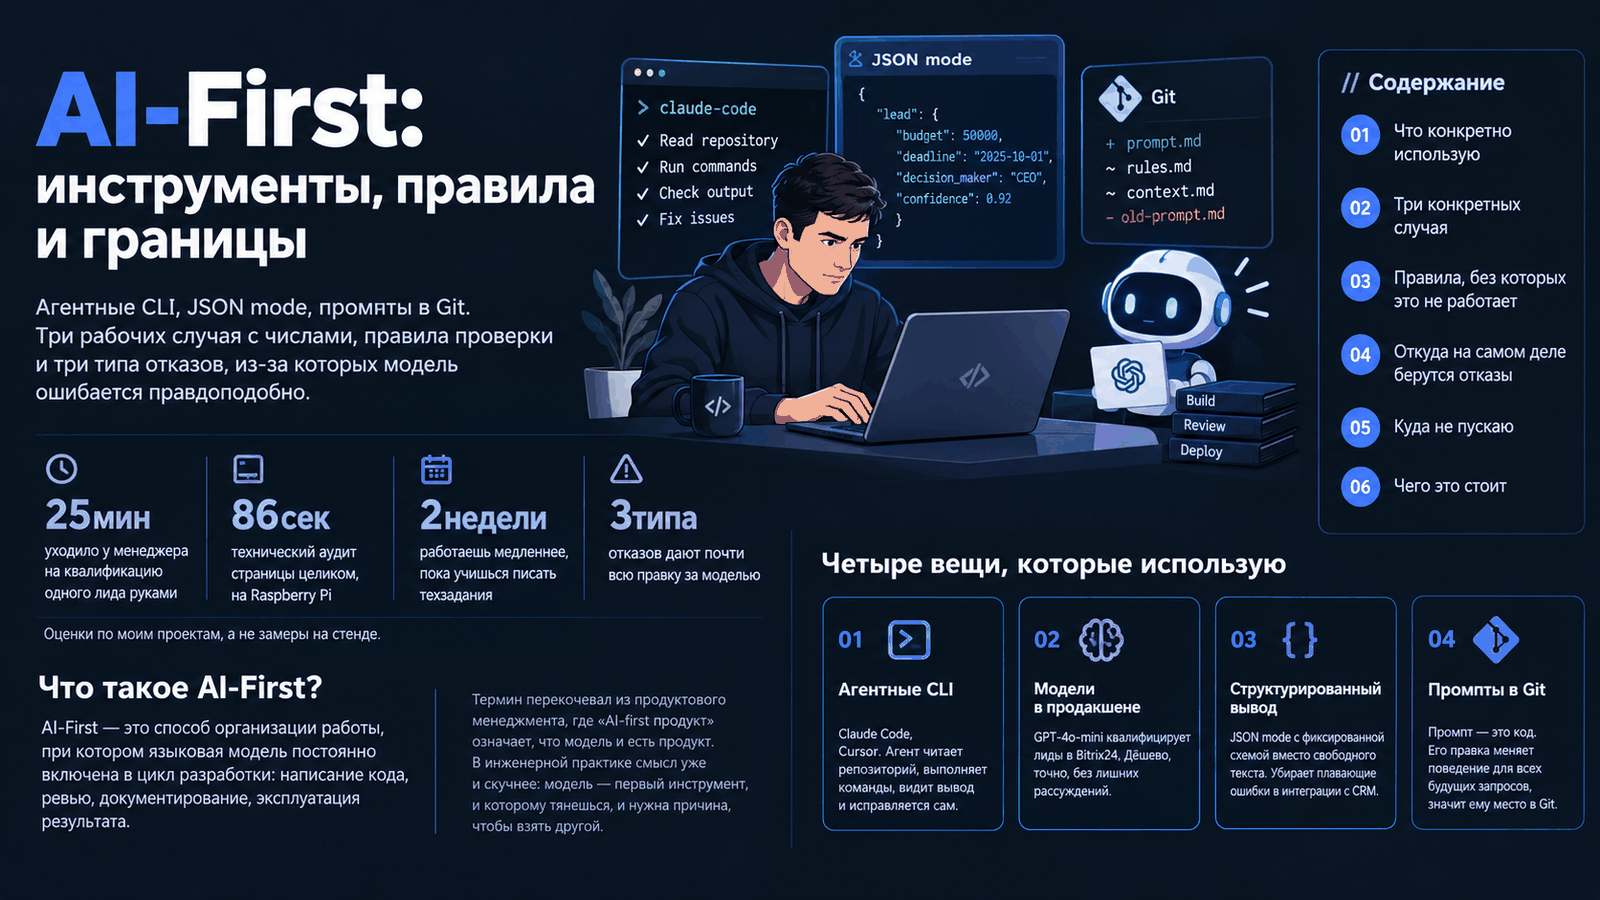
AI-First is a way of organising work where a language model is a permanent part of the development loop: writing code, reviewing it, documenting it, operating the result. The term migrated from product management, where "AI-first product" means the model is the product. In engineering practice it means something narrower and more boring: the model is the first tool you reach for, and you need a reason to reach for a different one.
Estimates from my own projects, not bench numbers.
What I actually run
Four things, in descending order of how much time they save me:
- Agentic CLI tools — Claude Code, Cursor. The distinction from a chat window matters: an agent reads the repository, runs commands, sees the output and corrects itself. A chat window gets a paragraph of context and guesses.
- Models in production — GPT-4o-mini classifying inbound leads in Bitrix24. Cheap enough to run on every lead, accurate enough for extraction and classification. Reasoning-grade models are wasted here.
- Structured output — JSON mode with a fixed schema, never free-form text I then parse with regexes. This single change removed most of the flakiness from the CRM integration.
- Prompts in Git — a prompt is code. Changing it changes behaviour for every future request, so it belongs in version control with a diff and a rollback.
Three concrete cases
Lead qualification. Sales spent 20–30 minutes per lead collecting budget, timeline, decision maker. Now a webhook fires on lead creation, the model extracts those fields into JSON, and the CRM shows them as deal fields. Confidence below a threshold flags for manual review instead of guessing.
SEO audit. The Python engine collects facts: response codes, meta tags, heading structure, broken links, robots.txt. Deterministic work, no model involved. The model then converts that pile of facts into text a client without a technical background can act on. Division of labour: measurement is code, explanation is the model.
Infrastructure. Deploying self-hosted storage on a Raspberry Pi — Docker, reverse proxy, ACME certificates, firewall rules, backup with verification. An evening instead of a weekend, and the documentation came out better than what I write when I'm tired at the end of a build.
Rules that make it work
A prompt is a specification. "Make it better" returns something. "Rewrite this function so failures return a typed error instead of null, preserve the signature, add a test for the empty-input case" returns what I wanted. Most of the complaints about model quality I hear are complaints about specification quality.
The model's output is an input to verification. For anything deterministic — migrations, money, access control — verification means tests, not reading it over. Reading catches obvious mistakes. Tests catch the other kind.
If I can't explain a line, it doesn't ship. This is the constraint that keeps AI-First from degrading into copy-paste. It costs time on the way in and saves much more on the way out, because debugging code you never understood is the most expensive work there is.
Context is a budget, not a bucket. Dumping the whole repository into the window makes answers worse, not better. Relevant files, the actual error, the constraint — that's the payload.
Where the failures actually come from
Modern models rarely produce nonsense. They produce plausible things, which is a harder problem: plausible passes review. The specific failure modes I hit, in order of frequency:
- Invented signatures. A function that should exist, with arguments that would make sense, in a library that never had it.
- Stale configuration. Directives that were valid two major versions ago. Caddy and Docker Compose both bit me here — the answer looks right and fails validation.
- Confident wrong constants. Timeouts, limits, port numbers stated as fact. These are the dangerous ones: nothing crashes, the system just behaves subtly wrong.
The countermeasure is unglamorous — check against current documentation before applying anything that touches configuration.
Where I keep it out
Architecture decisions, anything touching money or personal data, and anything where being wrong is both expensive and invisible. Not because the model can't produce an answer, but because I can't cheaply verify it, and unverifiable output at those stakes is a liability.
What it costs
Money: less than a junior's day rate, per month. Time: the first two weeks are slower, because writing specifications is a skill and most developers, myself included, arrive underqualified at it.
The honest summary is that AI-First moves effort from typing to specifying and verifying. If you like those two activities less than typing, it will feel worse. If the interesting part of the job was always deciding what to build, it buys you more of it.